Mogul AI crestMOGUL AI Put AI to work
12 Oct Meta — Muse Wonder and Muse Wonder Full released7 Oct Anthropic — Claude Haiku 5.5 launches at $0.10 / $0.506 Oct Mistral — Mistral Large 4 enters public preview1 Oct Microsoft — Microsoft ships streaming transcription and MAI-Voice-2.130 Sep Google — Gemini 4 Argon announced29 Sep OpenAI — GPT-6.1 Sol arrives in the API28 Sep Anthropic — Claude Sonnet 5.5 released22 Sep Anthropic — Claude Opus 5.5 released

AI Model Observatory · data as of

Who is actually winning the AI race — by job, with receipts.

29 frontier models from 15 labs, compared on intelligence, coding, price, speed, open weights and voice. Every number links to where it came from. Where we could not verify a figure you see a dash — never a guess.

Mogul AI

The six verdictsThere is no single winner — there is a winner per job

01Best overall reasoning

Claude Opus 5.5

Anthropic

Scores 58 at max effort.

Next: Claude Sonnet 5.5 56, Muse Wonder Full 56, Claude Fable 5.1 53.

Caveat At that setting it costs $5.98 per index task and waits 691.7s before the first token.

How we scored it

Highest Artificial Analysis Intelligence Index (independent).

Evidence as of 13 Oct 2026 · Artificial Analysis

02Best coding

Claude Sonnet 5.5

Anthropic

70.6%.

Next: Claude Opus 5.5 66.4%, GPT-6 Astra 57.9%, Claude Fable 5.1 55.8%.

Caveat Every Terminal-Bench figure here is vendor-reported; we could not load an independent coding leaderboard on this date. On a different test, DeepSWE v1.1, Gemini 4 Argon leads at 77.9% (also vendor-reported) — so this verdict is contested.

How we scored it

Highest Terminal-Bench 4.0 resolution rate — the coding test inside the AA index.

Evidence as of 13 Oct 2026 · Anthropic · Anthropic · Anthropic

03Best value per dollar

MiMo-V2.6-Pro

Xiaomi (MiMo)

Index 46 at $0.13 per task = 354 points per dollar.

Next: Claude Haiku 5.5 (max) 205, GPT-6.1 Sol (high) 156, Claude Opus 5.5 (medium) 38.

Caveat Among the eleven major labs the pick is Claude Haiku 5.5 (max): index 43 at $0.21 per task (205 points per dollar).

How we scored it

Most AA index points per dollar of AA cost-per-task, among settings scoring 40 or higher.

Evidence as of 13 Oct 2026 · Artificial Analysis

04Fastest

Muse Spark 1.3 (xhigh)

Meta

245 tokens/sec at index 45, first token after 22.3s.

Next: Claude Haiku 5.5 (max) 237.9, Gemini 3.8 Flash (high) 141.4, Claude Sonnet 5.5 (max) 135.

Caveat Raw speed champion regardless of intelligence: Celeris-1 at 1,522 tokens/sec, index 6.

How we scored it

Highest measured output tokens per second among settings scoring 40 or higher on the AA index.

Evidence as of 13 Oct 2026 · Artificial Analysis

05Best open-weight

MiMo-V2.6-Pro

Xiaomi (MiMo)

Index 46, licence: MIT.

Next: GLM-5.3 45 (GLM-5.3 License (commercial use with restrictions)), Kimi K3 44 (Kimi K3 License (commercial use with restrictions)), DeepSeek V4.1 Flash 39 (MIT).

Caveat Open weights means you may host it yourself; check each licence — several allow commercial use only with restrictions.

How we scored it

Highest AA Intelligence Index among models whose weights are published.

Evidence as of 13 Oct 2026 · Artificial Analysis

06Best for voice / agents

GPT-Live-1 (Astra, medium)

OpenAI

Index 83.2, 74.5% on the agentic voice test, first audio in 1.34s, about $5.83 per hour.

Next: Gemini 3.8 Live Extended Thinking (High) 82.6, Grok Voice Think Fast 2.0 High 81.3. Cheapest in the top six: Gemini 3.8 Live at $0.84 per hour.

Caveat For text agents doing office work, Claude Opus 5.5 leads GDPval-AA at 1,846 Elo, ahead of Claude Sonnet 5.5 at 1,844.

How we scored it

Highest Artificial Analysis Speech-to-Speech Index (reasoning, conversation flow and tool use, measured by voice).

Evidence as of 13 Oct 2026 · Artificial Analysis

Labs tracked

15

11 major, 4 to watch

Models in focus

29

28 independently scored

Top intelligence score

58

Claude Opus 5.5

Latest model release

12 Oct

Muse Wonder Full

Cheapest capable output / 1M

$0.50

Claude Haiku 5.5 · index 43

Labs
Lens
Reasoning

29/ 29

02The picture

See the race, not just the table

Flip the switches above and every chart and the leaderboard redraw together. Each mark is a figure from the data file; a model with no verified figure is left out of that chart and named underneath it. Click any model to send it to the compare tray.

Intelligence vs price

The value frontier

Up and to the left is better: smarter for less. Models on the line have nothing both smarter and cheaper. The price axis is logarithmic — each labelled gridline is ten times the last.

  • Closed weights
  • Open weights
  • Not verified
  • Value frontier

Speed

Output speed

Release timeline

Who shipped, and when

One lane per lab, newest shipper on top. Dates are to scale.

03Frontier model leaderboard

Every figure, every source

Click a column to sort. Index is the Artificial Analysis Intelligence Index — higher is better. Prices are US dollars per million tokens. A † marks a figure with a caveat; hover or tap it. A dash means no verified figure.

Frontier AI model leaderboard — 29 models, data as of 13 Oct 2026
Claude Opus 5.5maxAnthropicClosed5866.4%†1,846†$4$20$5.981M95.2691.7s†2026-09-22
Claude Sonnet 5.5maxAnthropicClosed5670.6%†1,844†$2$10$5.461M135451.9s2026-09-28
Muse Wonder FullmaxMetaClosed56—————1M——2026-10-12
Claude Fable 5.1maxAnthropicClosed5355.8%†1,735†$10$50$7.631M68246.6s2026-09-01†
GPT-6 AstramaxOpenAIClosed5357.9%†1,542†$10$50$3.261.05M63326.1s2026-09-03†
Gemini 4 ArgonhighGoogle / DeepMindClosed53——$2†$10†$1.991M——2026-09-30†
GPT-6.1 SolmaxOpenAIClosed52——$2$10$0.721.05M65321.8s2026-09-29†
Muse WondermaxMetaClosed52——$4†$20†$4.521M†101.419.7s2026-10-12
Muse Spark 1.3maxMetaClosed48——$1.25†$4.25†$1.601M123.940.8s2026-09-02
Grok 4.7xhighxAI (SpaceXAI)Closed4637.6%†1,695†$2†$6†$3.74500k83.887.0s2026-09-21
MiMo-V2.6-ProreasoningXiaomi (MiMo)Open46——$0.43$0.87$0.131M47.93.7s2026-09-21†
Qwen3.8 MaxreasoningAlibaba (Qwen)Closed45——$2†$6$5.41984k40.62.9s2026-09-02†
GLM-5.3maxZ AI (GLM)Open45——$1.40$4.40$2.011M66.93.3s2026-08-18†
Kimi K3maxMoonshot AI (Kimi)Open44——$3†$15$21.04858M433.1s2026-07-16
Claude Haiku 5.5maxAnthropicClosed4339.2%†1,620$0.10†$0.50†$0.211M237.9309.8s†2026-10-07
Gemini 3.8 FlashhighGoogle / DeepMindClosed41——$0.75†$3.75†$1.241M141.422.7s2026-09-02
DeepSeek V4.1 FlashmaxDeepSeekOpen39——$0.30†$1.20†$0.271M197.31.1s2026-09-10
GPT-6 LunamaxOpenAIClosed3816.4%†1,437$0.10$0.50—1.05M134.2113.3s2026-09-22
Mistral Large 4previewMistralClosed3828.3%†—$1.36$4.18$1.13524k——2026-10-06
DeepSeek V4 Pro 0813maxDeepSeekOpen36——$1.32†$3.96†$0.671M951.7s2026-08-13†
Qwen3.8 27BxhighAlibaba (Qwen)Open34——$0.50†$3$1.01256k45.93.8s2026-08-14†
Kimi K2.7 CodedefaultMoonshot AI (Kimi)—26——$0.95†$4$0.54262.144k752.8s—
Gemini 3.5 Flash-LitedefaultGoogle / DeepMind—22——$0.30$2.50$0.191M4087.9s—
Muse Glimmer 30BhighMetaOpen17——$0.33†$1.35$0.06131k133.81.0s2026-08-10
Gemma 4 31BreasoningGoogle / DeepMindOpen15—————256k35.51.0s2026-04-02
Nova 2.0 Pro (Preview)mediumAmazonClosed14est†——$1.38†$11—256k12213.2s2025-11-27
Mercury 2.5reasoningInceptionClosed12——$0.25$0.75$0.12260k705.83.4s2026-09-08
Mistral Small 4reasoningMistral—11————$0.02256k1580.8s—
Celeris-1defaultCeleris—6————$0.05131k1,5220.6s—

The input filter only matches models whose input types we verified; unverified models drop out when you pick one. “est” = Artificial Analysis marks the score as an estimate. 214 of 493 tracked data points are blank for lack of a verifiable source.

04Head to head

Put two to four in the ring

Pick models here, from the leaderboard, or by clicking any chart. The radar is relative to your picks: on each spoke the best of the models you chose reaches the rim and the others are drawn as their true share of it.

    05For business owners

    Which model for my job?

    Pick the job. The answer is computed from the data on this page, so it moves when the leaderboard moves.

    06Voice agents

    Models that talk

    Speech-to-speech models are scored separately. S2S index and the agentic score come from Artificial Analysis; cost is per hour of input audio.

    Voice modelLabS2S indexAgenticFirst audio$ / hour
    GPT-Live-1 (Astra, medium)OpenAI83.274.5%1.34s$5.83
    Gemini 3.8 Live Extended Thinking (High)Google / DeepMind82.668.6%1.35s$3.50
    Grok Voice Think Fast 2.0 HighxAI (SpaceXAI)81.356.5%0.7s$4.80
    GPT-Live-1 (Sol, low)OpenAI80.159.3%1.24s$4.47
    Gemini 3.8 LiveGoogle / DeepMind76.030.1%1.18s$0.84
    GPT-Realtime-2.1 HighOpenAI75.245.7%1.21s$10.75

    07The labs

    Newest models and latest move

    Anthropic

    • Claude Opus 5.5index 58 · 22 Sep 2026
    • Claude Sonnet 5.5index 56 · 28 Sep 2026
    • Claude Haiku 5.5index 43 · 7 Oct 2026
    • Claude Fable 5.1index 53 · 1 Sep 2026

    Latest · 7 Oct 2026Shipped Claude Haiku 5.5 at $0.10 / $0.50 per million tokens for prompts up to 100k tokens — a tenth of the previous Haiku's price. source

    OpenAI

    • GPT-6 Astraindex 53 · 3 Sep 2026
    • GPT-6.1 Solindex 52 · 29 Sep 2026
    • GPT-6 Lunaindex 38 · 22 Sep 2026

    Latest · 29 Sep 2026GPT-6.1 Sol is listed in the API at $2 / $10 per million tokens, described by OpenAI as near-Astra performance at lower cost. source

    Google / DeepMind

    • Gemini 4 Argonindex 53 · 30 Sep 2026
    • Gemini 3.8 Flashindex 41 · 2 Sep 2026
    • Gemini 3.5 Flash-Liteindex 22 · —
    • Gemma 4 31Bindex 15 · 2 Apr 2026

    Latest · 30 Sep 2026Announced Gemini 4 Argon. Access starts with vetted cyber defenders, then paid API customers and AI Ultra subscribers; introductory price $2 / $10. source

    Meta

    • Muse Wonder Fullindex 56 · 12 Oct 2026
    • Muse Wonderindex 52 · 12 Oct 2026
    • Muse Spark 1.3index 48 · 2 Sep 2026
    • Muse Glimmer 30Bindex 17 · 10 Aug 2026

    Latest · 12 Oct 2026Released Muse Wonder (Meta Model API and Muse Code) and Muse Wonder Full (Muse Code subscribers only). source

    xAI (SpaceXAI)

    • Grok 4.7index 46 · 21 Sep 2026

    Latest · 21 Sep 2026Released Grok 4.7 at $2 / $6 per million tokens, with a fast variant at twice the speed and twice the price. source

    Mistral

    • Mistral Large 4index 38 · 6 Oct 2026
    • Mistral Small 4index 11 · —

    Latest · 6 Oct 2026Put Mistral Large 4 (1 trillion parameters, 52B active) into public preview at $1.36 / $4.18; open weights promised by the end of October 2026. source

    DeepSeek

    • DeepSeek V4.1 Flashindex 39 · 10 Sep 2026
    • DeepSeek V4 Pro 0813index 36 · 13 Aug 2026

    Latest · 10 Sep 2026Released DeepSeek V4.1 Flash with weights on Hugging Face; off-peak API rates are half of peak. source

    Moonshot AI (Kimi)

    • Kimi K3index 44 · 16 Jul 2026
    • Kimi K2.7 Codeindex 26 · —

    Latest · 16 Jul 2026Kimi K3 (2.8T parameters, 104B active) is the current flagship, with open weights under the Kimi K3 License. source

    Alibaba (Qwen)

    • Qwen3.8 Maxindex 45 · 2 Sep 2026
    • Qwen3.8 27Bindex 34 · 14 Aug 2026

    Latest · 2 Sep 2026Qwen3.8 Max (0902 snapshot) lists at $2 / $6 on Alibaba Cloud's international region. source

    Amazon

    • Nova 2.0 Pro (Preview)index 14 · 27 Nov 2025

    Latest · 27 Nov 2025Nova 2.0 Pro remains in preview; Artificial Analysis still marks its intelligence score as an estimate. source

    Microsoft

    • No frontier chat model tracked in the leaderboard

    Latest · 1 Oct 2026Launched MAI-Transcribe-2-Streaming ($0.54 per audio hour, introductory) plus MAI-Voice-2.1 ($22 per million characters) and a Flash voice ($15). Microsoft's current first-party push is voice, not a frontier chat model. source

    Z AI (GLM)

    • GLM-5.3index 45 · 18 Aug 2026

    Latest · 18 Aug 2026GLM-5.3 scores 45 on the Artificial Analysis index with open weights. source

    Xiaomi (MiMo)

    • MiMo-V2.6-Proindex 46 · 21 Sep 2026

    Latest · 21 Sep 2026MiMo-V2.6-Pro: MIT-licensed open weights scoring 46 on the Artificial Analysis index at $0.13 per index task. source

    Inception

    • Mercury 2.5index 12 · 8 Sep 2026

    Latest · 8 Sep 2026Mercury 2.5 measured at 705.8 output tokens per second. source

    Celeris

    • Celeris-1index 6 · —

    Latest · —Celeris-1 measured at 1,522 output tokens per second — the fastest row on the leaderboard, with a low intelligence score. source

    08On the radar

    The last 60 days

    1. Meta

      Muse Wonder and Muse Wonder Full released

      Wonder is on the Meta Model API and Muse Code; Wonder Full is limited to Muse Code subscribers. Artificial Analysis scores Wonder Full at 56, tied for second overall.

      Meta — Muse Wonder announcement · lab announcement

    2. Anthropic

      Claude Haiku 5.5 launches at $0.10 / $0.50

      Two price tiers split at 100k prompt tokens. Artificial Analysis scores it 43 at 237.9 tokens per second.

      Anthropic — Claude Haiku 5.5 announcement · lab announcement

    3. Mistral

      Mistral Large 4 enters public preview

      A 1-trillion-parameter multimodal model at $1.36 / $4.18. Mistral says open weights follow by the end of October.

      Mistral — Mistral Large 4 announcement · lab announcement

    4. Microsoft

      Microsoft ships streaming transcription and MAI-Voice-2.1

      MAI-Transcribe-2-Streaming covers 60 languages at $0.54 per audio hour (introductory); two new text-to-speech voices at $22 and $15 per million characters.

      Microsoft AI — streaming transcription and MAI-Voice-2.1 announcement · lab announcement

    5. Google

      Gemini 4 Argon announced

      Introductory $2 / $10, rising to $4 / $20. Google reports 77.9% on DeepSWE v1.1. Rollout starts with vetted cyber defenders; not generally available yet.

      Google — Gemini 4 Argon announcement · lab announcement

    6. OpenAI

      GPT-6.1 Sol arrives in the API

      Listed at $2 / $10 with a 1.05M-token context. Artificial Analysis scores it 52 at $0.72 per index task.

      OpenAI — GPT-6.1 Sol model page · date from release tracker

    7. Anthropic

      Claude Sonnet 5.5 released

      $2 / $10. Anthropic reports 70.6% on Terminal-Bench 4.0, above its own Opus 5.5.

      Anthropic — Claude Sonnet 5.5 announcement · lab announcement

    8. Anthropic

      Claude Opus 5.5 released

      $4 / $20. Tops the Artificial Analysis Intelligence Index at 58.

      Anthropic — Claude Opus 5.5 announcement · lab announcement

    9. OpenAI

      GPT-6 Sol and GPT-6 Luna released

      Luna is the low-cost tier at $0.10 / $0.50; Artificial Analysis scores it 38.

      Artificial Analysis — GPT-6 Luna · date from release tracker

    10. xAI

      Grok 4.7 released

      $2 / $6 with a 500k-token context. xAI reports 71.0% on DeepSWE v1.1 and 37.6% on Terminal-Bench 4.0.

      xAI — Grok 4.7 announcement · lab announcement

    11. Industry

      Subscribers sue four labs over an alleged pact to slow AI development

      After Anthropic's CEO published a 12 September essay urging the industry to pace frontier work — backed the same day by the heads of OpenAI, xAI and Google DeepMind — paying subscribers filed a proposed class action in the Northern District of California alleging illegal coordination. No ruling has been made.

      Euronews — AI labs sued over alleged slowdown pact (21 Sep 2026) · press report

    12. DeepSeek

      DeepSeek V4.1 Flash released with open weights

      A 552B-parameter mixture-of-experts model. Artificial Analysis scores it 39 at 197.3 tokens per second and lists the licence as MIT.

      DeepSeek — V4.1 Flash release note · lab announcement

    13. OpenAI

      GPT-6 Astra released

      OpenAI's top tier at $10 / $50. Artificial Analysis scores it 53.

      OpenAI — GPT-6 Astra model page · date from release tracker

    14. Google

      Gemini 3.8 Flash released; price doubles in January

      $0.75 / $3.75 through 31 December 2026, then $1.50 / $7.50 from 1 January 2027.

      Google — Gemini 3.8 Flash announcement · lab announcement

    15. Anthropic

      Claude Fable 5.1 released; Mythos 5.1 stays restricted

      Fable 5.1 is $10 / $50. Mythos 5.1 is offered only through verified cyber and life-science programs.

      Anthropic — Claude Fable 5.1 and Mythos 5.1 announcement · date from release tracker

    Mogul AI

    You do not need to track any of this.

    We pick the right model for each job in your business, wire it to your phones, website and follow-up, and keep it current as the leaderboard changes.

    See what Mogul AI runs for you

    09Method

    How we score

    Each “Who's winning” verdict is a single stated rule applied to the table — no editorial weighting. A model counts as “capable” for the value and speed verdicts when it scores 40 or higher on the Artificial Analysis Intelligence Index. Scores marked as estimates are excluded from every verdict and from the price chart.

    • AA Intelligence Index: Artificial Analysis Intelligence Index v4.3.2 — independent. Weighted mix: agents 30% (AA-Briefcase, GDPval-AA, AutomationBench-AA), coding 20% (Terminal-Bench 4.0, SciCode), general 30% (AA-Omniscience, GDP.pdf, AA-LCR), scientific reasoning 20% (HLE, CritPt).
    • AA cost per index task: Artificial Analysis — average USD cost to run one Intelligence Index task at the listed reasoning setting. Independent.
    • Speed, tokens / sec: Artificial Analysis — median output tokens per second on the vendor's own API. Independent.
    • Time to first token, sec: Artificial Analysis — seconds until the first answer token, including thinking time. Independent.
    • Terminal-Bench 4.0 %: Terminal-Bench 4.0 resolution rate (agentic coding in a terminal). Figures here are vendor-reported.
    • GDPval-AA Elo: GDPval-AA v2.1 Elo (real-world knowledge-work tasks), run by Artificial Analysis; figures here were read from vendor announcement pages.
    • DeepSWE v1.1 %: DeepSWE v1.1 (software engineering). Vendor-reported.
    • SWE-bench Verified %: SWE-bench Verified. Not populated — see field notes.
    • Arena text Elo: Arena (formerly LMArena) text Elo. Not populated — see field notes.

    Independent measurements are preferred over a lab's own claims. Where only the lab has published a number, it is labelled vendor-reported. Where two sources disagree, both are kept in the note on that figure. Release dates taken from a tracker rather than the lab's own page are flagged as such.

    Charts are drawn to scale from the same data file as the table. Nothing is interpolated: a model with no verified figure for a chart is left out of it and listed in the line beneath. The Reasoning switch set to Low swaps in the lowest reasoning setting Artificial Analysis measured, for the models where one was measured; the rest stay at their only measured setting.
    10Sources

    46 sources, all fetched 13 Oct 2026

    1. Artificial Analysis — Claude Haiku 5.5 Independent benchmark · fetched 2026-10-13
    2. Artificial Analysis — Claude Opus 5.5 Independent benchmark · fetched 2026-10-13
    3. Artificial Analysis — DeepSeek V4.1 Flash Independent benchmark · fetched 2026-10-13
    4. Artificial Analysis — GLM-5.3 Independent benchmark · fetched 2026-10-13
    5. Artificial Analysis — GPT-6 Luna Independent benchmark · fetched 2026-10-13
    6. Artificial Analysis — Gemini 3.8 Flash Independent benchmark · fetched 2026-10-13
    7. Artificial Analysis — Gemini 4 Argon Independent benchmark · fetched 2026-10-13
    8. Artificial Analysis — Gemma 4 31B Independent benchmark · fetched 2026-10-13
    9. Artificial Analysis — Grok 4.7 Independent benchmark · fetched 2026-10-13
    10. Artificial Analysis — Intelligence Index methodology Independent benchmark · fetched 2026-10-13
    11. Artificial Analysis — Kimi K3 Independent benchmark · fetched 2026-10-13
    12. Artificial Analysis — LLM leaderboard (Intelligence Index v4.3.2) Independent benchmark · fetched 2026-10-13
    13. Artificial Analysis — Mercury 2.5 Independent benchmark · fetched 2026-10-13
    14. Artificial Analysis — MiMo-V2.6-Pro Independent benchmark · fetched 2026-10-13
    15. Artificial Analysis — Mistral Large 4 Independent benchmark · fetched 2026-10-13
    16. Artificial Analysis — Muse Glimmer Independent benchmark · fetched 2026-10-13
    17. Artificial Analysis — Muse Spark 1.3 Independent benchmark · fetched 2026-10-13
    18. Artificial Analysis — Muse Wonder Independent benchmark · fetched 2026-10-13
    19. Artificial Analysis — Nova 2.0 Pro Independent benchmark · fetched 2026-10-13
    20. Artificial Analysis — Qwen3.8 27B Independent benchmark · fetched 2026-10-13
    21. Artificial Analysis — Qwen3.8 Max Independent benchmark · fetched 2026-10-13
    22. Artificial Analysis — Speech-to-Speech leaderboard Independent benchmark · fetched 2026-10-13
    23. Alibaba Cloud — Model Studio pricing Lab's own page · fetched 2026-10-13
    24. Anthropic — Claude Fable 5.1 and Mythos 5.1 announcement Lab's own page · fetched 2026-10-13
    25. Anthropic — Claude Haiku 5.5 announcement Lab's own page · fetched 2026-10-13
    26. Anthropic — Claude Opus 5.5 announcement Lab's own page · fetched 2026-10-13
    27. Anthropic — Claude Sonnet 5.5 announcement Lab's own page · fetched 2026-10-13
    28. Anthropic — Models overview (pricing, context, IDs) Lab's own page · fetched 2026-10-13
    29. DeepSeek — API pricing Lab's own page · fetched 2026-10-13
    30. DeepSeek — V4.1 Flash release note Lab's own page · fetched 2026-10-13
    31. Google — Gemini 3.8 Flash announcement Lab's own page · fetched 2026-10-13
    32. Google — Gemini 4 Argon announcement Lab's own page · fetched 2026-10-13
    33. Google — Gemini API pricing Lab's own page · fetched 2026-10-13
    34. Meta — Muse Wonder announcement Lab's own page · fetched 2026-10-13
    35. Meta — Muse model API page Lab's own page · fetched 2026-10-13
    36. Microsoft AI — streaming transcription and MAI-Voice-2.1 announcement Lab's own page · fetched 2026-10-13
    37. Mistral — Mistral Large 4 announcement Lab's own page · fetched 2026-10-13
    38. Moonshot / Kimi — API pricing Lab's own page · fetched 2026-10-13
    39. OpenAI — API pricing Lab's own page · fetched 2026-10-13
    40. OpenAI — GPT-6 Astra model page Lab's own page · fetched 2026-10-13
    41. OpenAI — GPT-6.1 Sol model page Lab's own page · fetched 2026-10-13
    42. OpenAI — Models Lab's own page · fetched 2026-10-13
    43. xAI — Grok 4.7 announcement Lab's own page · fetched 2026-10-13
    44. xAI — Models and pricing Lab's own page · fetched 2026-10-13
    45. BenchLM — model release tracker (aggregator; dates are claims) Aggregator · fetched 2026-10-13
    46. Euronews — AI labs sued over alleged slowdown pact (21 Sep 2026) Press · fetched 2026-10-13

    From Adapt Target Marketing

    The same team, other arenas

    Train Smarter. Perform Stronger. Recover Faster.

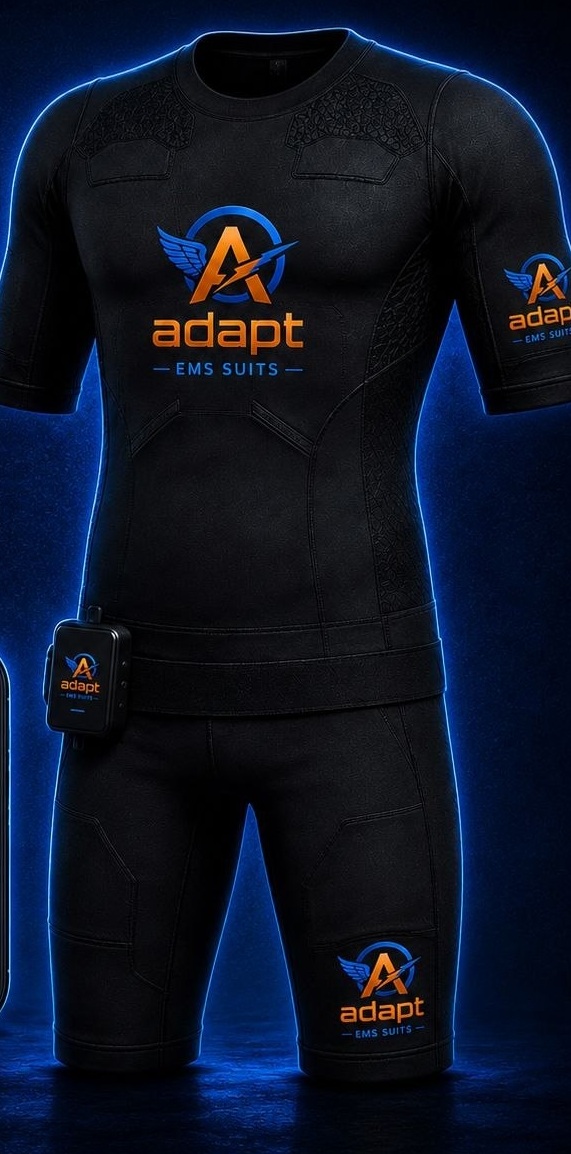
    Wireless EMS training suit — 20-minute full-body sessions, app included, no monthly subscription.

    The Adapt EMS Dry Suit — a black wireless EMS training suit with the Adapt EMS Suits logo on the chest.

    See the suits adaptemssuits.com